Mastering Kubernetes CronJobs: Avoiding Overlaps and Handling Deadlines
Intermediate · 10 min read
Key takeaways
- Use concurrencyPolicy: Forbid to prevent resource contention when jobs exceed their schedule interval.
- Use concurrencyPolicy: Replace to prioritize the latest data execution, canceling slower previous runs.
- Always set activeDeadlineSeconds in Job templates to prevent indefinite hangs and resource leaks.
- Ensure application idempotency and proper backoff limits to handle transient failures gracefully.
The Problem
In the world of DevOps, predictability is currency. You have a critical data synchronization job that must run every hour to keep your analytics dashboard accurate. You configure a Kubernetes CronJob with a schedule of * * * * *. Everything looks perfect in the YAML file. However, on a particularly busy Tuesday, network latency spikes, or the database connection pool becomes saturated. The job takes longer than expected—say, 65 minutes instead of the usual 10. Because the schedule is strict, Kubernetes attempts to start a second instance exactly one minute after the first. Now you have two jobs running simultaneously, both fighting for the same database resources. This leads to race conditions, duplicate data entries, database lock timeouts, and potentially corrupted state.
This scenario highlights a fundamental pain point in automated orchestration: the assumption that tasks are instantaneous. In reality, production workloads are variable. Without explicit configuration, Kubernetes will happily spawn overlapping instances of a CronJob, leading to resource contention and logical errors. The problem is not just about efficiency; it is about data integrity and system stability. As systems scale, the probability of overlap increases, especially when maintenance windows align with high-traffic periods. Understanding how to prevent these overlaps is not optional for serious infrastructure management; it is a requirement for reliable automation.
Core Concepts
To solve the overlap problem, we must first understand the mechanics behind Kubernetes CronJobs. A CronJob is a Kubernetes object that creates Jobs on a repeating schedule. It does not run the task directly; rather, it acts as a scheduler that triggers the creation of Job objects, which in turn create Pods (the actual containers running your code).
The behavior of a CronJob regarding concurrent execution is governed by two primary fields in its specification:
concurrencyPolicy: This field dictates what happens when a new scheduled time arrives while a previous Job is still running. There are three standard policies:Allow(Default): Multiple Jobs may run concurrently. This is the source of our problem.Forbid: If a Job is already running, the new schedule is skipped entirely. No new Job is created until the current one finishes.Replace: The currently running Job is canceled, and a new one is started immediately. This ensures the latest data is processed but risks losing partial work from the previous instance.
successfulJobsHistoryLimitandfailedJobsHistoryLimit: These control how many completed or failed Jobs are kept in the cluster for inspection. While not directly causing overlaps, they impact storage and cleanup efficiency.- Deadlines and Timeouts: Unlike standard Jobs, CronJobs do not have a native “activeDeadlineSeconds” field in their own spec. Instead, timeout handling is often managed at the Pod level via
activeDeadlineSecondswithin the Job template, or through external monitoring. However, the concept of a “deadline” refers to the maximum acceptable duration for a single execution cycle before it is considered stale or problematic.
Understanding these concepts allows us to move from passive scheduling to active conflict resolution. We are essentially choosing between consistency (skipping runs), freshness (replacing old runs), or chaos (allowing all runs).
Jargon Definition
- Job: An object that manages one-time tasks or parallel tasks, ensuring a specified number of Pods terminate successfully.
- Pod: The smallest deployable unit in Kubernetes, containing one or more containers.
- Schedule: A cron-expression string defining when the Job should trigger (e.g.,
*/5 * * * *for every 5 minutes). - Concurrency: The ability of multiple instances of a process to exist at the same time.
How It Works
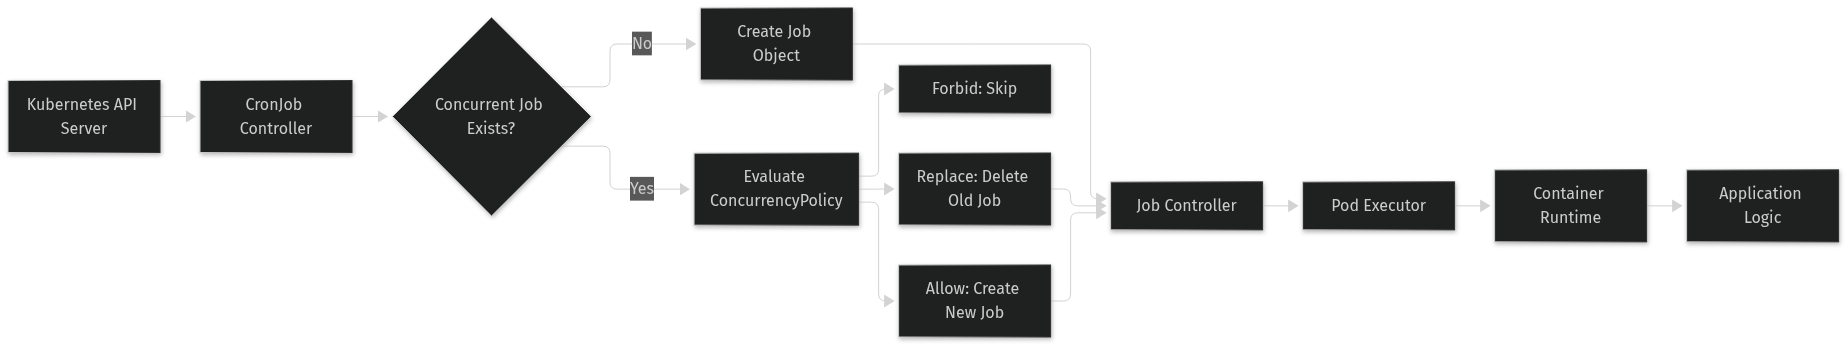
The lifecycle of a CronJob involves several distinct steps that occur within the Kubernetes control plane. When the CronJob controller detects a matching schedule time, it checks the existing state of Jobs associated with that CronJob.
First, it identifies any active Jobs. An active Job is one whose Pods are still running or restarting. If concurrencyPolicy is set to Forbid, the controller immediately aborts the creation of a new Job if it finds even one active Job from a previous schedule. This check is atomic and happens before any resources are allocated for the new task. This prevents the race condition described earlier by simply ignoring the late trigger.
If the policy is Replace, the controller performs a more aggressive action. It identifies the active Job and deletes it. Deleting the Job signals the termination of its Pods. Simultaneously, it creates a new Job object. This ensures that the most recent schedule wins, but it comes with the cost of interrupting ongoing work. This is useful for tasks where the latest data snapshot is always preferred over completing a stale calculation.
If the policy is Allow (default), no checks are performed. The controller creates a new Job regardless of the state of previous ones. This is suitable for idempotent operations—tasks that can be safely repeated without side effects, such as sending a notification email or querying a read-only API.
It is crucial to note that Kubernetes relies on the system clock. If the node’s clock drifts significantly, or if the API server is under heavy load, the timing of these checks might vary slightly. However, for most operational use cases, the millisecond-level precision is sufficient to enforce concurrency policies effectively.
Prerequisites
Before implementing these configurations, ensure you have the following:
- Kubernetes Cluster Access: A working cluster (v1.19+ recommended for stable CronJob behavior). You need
kubectlconfigured with appropriate permissions to create and manage Jobs. - Docker Container Image: A container image containing the script or application you wish to schedule. For this tutorial, we will use a simple Python script that simulates a long-running task.
- Basic Kubernetes Knowledge: Familiarity with creating namespaces, applying YAML manifests, and viewing logs.
- Namespace: We will use a dedicated namespace
cron-demoto isolate our experiments from other cluster workloads.
Hands-On Walkthrough
We will compare the three concurrency policies using a simulated long-running task. Our task is a Python script that sleeps for 45 seconds to simulate processing time. Since our schedule will be every 30 seconds, any policy other than Allow will trigger the overlap logic.
Step 1: Create the Namespace
First, isolate our test environment.
kubectl create namespace cron-demo
kubectl config set-context --current --namespace=cron-demo
Step 2: Define the Simulation Script
Create a file named long_task.py:
import time
import sys

print("Starting task...")
time.sleep(45)
print("Task finished successfully.")
sys.exit(0)
Build a Docker image for this script. For simplicity in this tutorial, assume we have an image tagged as devopsengine/long-task:v1.
Step 3: Configure Concurrency Policy ‘Forbid’
This is the most common policy for data integrity. We create a CronJob named forbid-job that runs every 30 seconds. Because our task takes 45 seconds, the next schedule (at 30s) will find an active job and skip it.
apiVersion: batch/v1
kind: CronJob
metadata:
  name: forbid-job
spec:
  schedule: "*/30 * * * *"
  concurrencyPolicy: Forbid
  successfulJobsHistoryLimit: 3
  failedJobsHistoryLimit: 1
  jobTemplate:
    spec:
      template:
        spec:
          containers:
          - name: worker
            image: devopsengine/long-task:v1
            resources:
              limits:
                memory: "128Mi"
                cpu: "500m"
          restartPolicy: OnFailure
Apply this manifest:
kubectl apply -f forbid-cronjob.yaml
Step 4: Configure Concurrency Policy ‘Replace’
This policy prioritizes freshness. Create replace-cronjob.yaml:
apiVersion: batch/v1
kind: CronJob
metadata:
  name: replace-job
spec:
  schedule: "*/30 * * * *"
  concurrencyPolicy: Replace
  successfulJobsHistoryLimit: 3
  failedJobsHistoryLimit: 1
  jobTemplate:
    spec:
      template:
        spec:
          containers:
          - name: worker
            image: devopsengine/long-task:v1
            resources:
              limits:
                memory: "128Mi"
                cpu: "500m"
          restartPolicy: OnFailure
Apply this manifest:
kubectl apply -f replace-cronjob.yaml
Step 5: Configure Concurrency Policy ‘Allow’ (Default)
This demonstrates the problem. Create allow-cronjob.yaml:
apiVersion: batch/v1
kind: CronJob
metadata:
  name: allow-job
spec:
  schedule: "*/30 * * * *"
  # concurrencyPolicy: Allow is default, so we omit it
  successfulJobsHistoryLimit: 3
  failedJobsHistoryLimit: 1
  jobTemplate:
    spec:
      template:
        spec:
          containers:
          - name: worker
            image: devopsengine/long-task:v1
            resources:
              limits:
                memory: "128Mi"
                cpu: "500m"
          restartPolicy: OnFailure
Apply this manifest:
kubectl apply -f allow-cronjob.yaml
Verifying It Works
Now we observe the behavior. Wait at least 90 seconds to see multiple schedule cycles.
Check Active Jobs
List all Jobs in the namespace:
kubectl get jobs
You will likely see three groups of jobs: those ending in -forbid-, -replace-, and -allow-.
Analyze ‘Forbid’ Behavior
Look at the pods for the forbid job:
kubectl get pods | grep forbid
You should see only one pod running at a time. When the 30-second mark hits while the previous 45-second task is still active, no new pod is created. The output will show gaps in execution times, confirming that skips occurred.
Analyze ‘Replace’ Behavior
Check the pods for the replace job:
kubectl get pods | grep replace
You will notice pods being terminated and new ones starting rapidly. If you check the logs of the old pod, you might see it was interrupted. The new pod starts fresh. This confirms that the previous instance was replaced.
Analyze ‘Allow’ Behavior
Check the pods for the allow job:
kubectl get pods | grep allow
You will see multiple pods running simultaneously. Their statuses will show Running concurrently. This visual confirmation proves that concurrency was allowed, leading to potential resource contention.
Common Mistakes
1. Assuming ‘Forbid’ Prevents All Overlaps Forever
Why it happens: Users think ‘Forbid’ means the job will eventually catch up.
Reality: If a job consistently takes longer than its schedule interval, ‘Forbid’ will cause it to never run again once it falls behind. To fix this, increase the schedule interval or optimize the job duration.
2. Ignoring Resource Limits
Why it happens: Developers focus on concurrency policies but forget to set CPU/Memory limits in the Job template.
Reality: Even with ‘Allow’, unbounded resources can crash the node. Always define resources.limits to ensure fair sharing.
3. Confusing CronJob Schedule with Wall Clock Time
Why it happens: Schedules are based on the Kubernetes control plane’s timezone, which defaults to UTC.
Reality: If your team operates in EST, a schedule of 0 9 * * * (UTC) is 4 AM EST. Always double-check timezones in your logging and schedules.
4. Not Setting History Limits
Why it happens: Leaving history limits at their defaults (usually 3 for success, 1 for failure) is good, but sometimes users delete them entirely.
Reality: Accumulated Job objects consume etcd storage. Set reasonable limits to keep the cluster clean.
Going Further
In production environments, simple concurrency policies are often insufficient. Here are advanced considerations:
Handling Hard Deadlines
Kubernetes CronJobs do not have a built-in timeout field. If a job hangs indefinitely, it consumes resources forever. To mitigate this, add activeDeadlineSeconds to the Job template:
spec:
  jobTemplate:
    spec:
      activeDeadlineSeconds: 120
      template:
        spec:
          containers:
          - name: worker
            image: devopsengine/long-task:v1
This forces the Pod to be killed after 120 seconds, preventing infinite hangs. This complements concurrencyPolicy by ensuring that even if a job is stuck, it won’t block future executions indefinitely.
Idempotency and Retry Logic
Regardless of the concurrency policy, your application code should be idempotent. Use backoffLimit in the Job spec to handle transient failures. For example:
backoffLimit: 4
This retries the job up to 4 times before marking it as failed. Combined with Forbid, this ensures that if a job fails due to a temporary glitch, it gets a few chances to succeed before skipping the next window.
Alternative Approaches
External Schedulers (Apache Airflow/Kubeflow)
For complex workflows with dependencies, Kubernetes CronJobs are too simplistic. Tools like Apache Airflow provide DAG-based scheduling, allowing you to define that Job B runs only after Job A succeeds. They offer better visibility and retry mechanisms.
StatefulSets with Timers
For extremely precise timing requirements, some teams embed timers within the application logic inside a StatefulSet. This moves the scheduling logic out of Kubernetes and into the application, giving finer control but increasing operational complexity.
Cleanup
To remove all resources created in this tutorial:
kubectl delete namespace cron-demo
This command removes the namespace and all associated CronJobs, Jobs, and Pods. Verify deletion with:
kubectl get namespaces
The cron-demo namespace should no longer appear in the list.
Architecture
References
This article was written with AI assistance.