Pod Affinity and Anti-Affinity for High Availability Across Zones
Intermediate · 11 min read
Key takeaways
- Use RequiredDuringSchedulingIgnoredDuringExecution for strict high availability guarantees across zones.
- Always scope anti-affinity labelSelectors to specific app labels to avoid blocking unrelated pods.
- Ensure balanced resource capacity across all zones to prevent scheduling failures under anti-affinity rules.
The Problem
In the world of cloud-native computing, high availability is not just a metric; it is a business requirement. Imagine your application serves millions of requests per minute. Under normal conditions, your Kubernetes cluster handles this load with ease. However, infrastructure is not immune to failure. Network partitions, hardware faults, or maintenance events can take down entire data centers or availability zones (AZs). If your application’s pods are all scheduled within a single zone, that single point of failure can lead to a total service outage.
Traditional deployment strategies often place replicas close together for performance reasons, inadvertently creating fragility. When a zone goes dark, your entire service stack vanishes. The pain point here is clear: how do we distribute our workload intelligently across distinct failure domains while maintaining operational simplicity? We need a mechanism that forces the scheduler to spread pods apart when necessary, ensuring that no single hardware or network failure takes down more than a fraction of our capacity.
Core Concepts
To solve the distribution problem, Kubernetes provides two powerful scheduling primitives: Pod Affinity and Pod Anti-Affinity. These rules allow you to express constraints on where pods can be placed relative to other pods running in the cluster. Understanding these requires distinguishing between types of affinity and the operators used to enforce them.
Node Affinity vs. Pod Affinity: Node affinity binds a pod to specific nodes based on node labels (e.g., instance type, region). Pod affinity, however, looks at other pods. It asks, “Where should I place this pod relative to existing pods?” This distinction is crucial because we are trying to manage relationships between workloads, not just hardware specifications.
Soft vs. Hard Constraints: Both affinity types support two modes:
- RequiredDuringSchedulingIgnoredDuringExecution (Hard): The scheduler MUST satisfy this condition. If no node meets the criteria, the pod remains in a
Pendingstate indefinitely until the cluster changes or the rule is relaxed. This is strict enforcement. - PreferredDuringSchedulingIgnoredDuringExecution (Soft): The scheduler WILL try to satisfy this condition but will schedule the pod anyway if no suitable node is found, ignoring the preference. This provides flexibility when hard constraints cannot be met.
Topology Keys: This is the key enabler for zone-aware distribution. A topology key defines the scope of the affinity rule. Common keys include kubernetes.io/hostname (for host-level distribution) and topology.kubernetes.io/zone (for zone-level distribution). By using a topology key, you tell the scheduler, “Do not put my pods on nodes that share this specific label value.” For high availability across zones, we primarily care about the zone topology key.
Match Expressions vs. Match Fields: In modern Kubernetes, matchExpressions are preferred over matchFields because they are more flexible and performant. They allow you to specify operators like In, NotIn, Exists, and DoesNotExist to define complex logical conditions.
How It Works
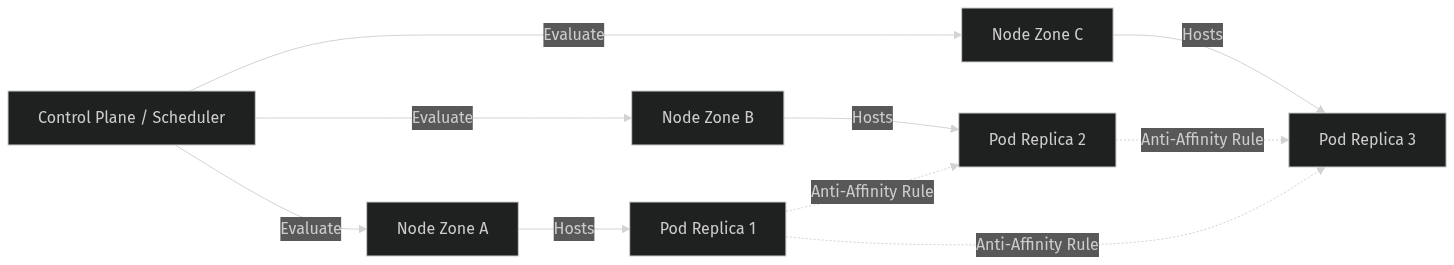
The mechanics of pod anti-affinity rely on the Kubernetes Scheduler, a control plane component responsible for assigning pods to nodes. When a pod is created, the scheduler evaluates the pending pods against available nodes. It filters out nodes that cannot run the pod (due to resource constraints or taints) and then scores the remaining nodes.
When a RequiredDuringSchedulingIgnoredDuringExecution anti-affinity rule is present, the scheduler performs a pre-filtering step. It queries the etcd datastore for all pods currently running in the cluster that match the specified selector (labels). For each candidate node, the scheduler checks if placing the new pod there would violate the anti-affinity rule. Specifically, it checks if any matching pods already exist on that node or on other nodes sharing the same topology key value (if configured).
If the rule specifies podAntiAffinity with a topology key of topology.kubernetes.io/zone, the scheduler ensures that for every pod selected by the rule, no other matching pod exists in the same zone. This effectively spreads the replica set across as many zones as possible. If you have three replicas and two zones, the scheduler might place two pods in Zone A and one in Zone B. If you add a third zone, it will balance them as evenly as possible (one per zone).
This process is iterative. As more pods are added, the scheduler continuously re-evaluates placement to maintain the desired distribution state. It does not actively move pods once scheduled unless forced by rescheduling events or manual intervention, which is why initial placement accuracy is critical.
Prerequisites
Before implementing zone-aware anti-affinity, ensure you have the following:
- A Multi-Zone Cluster: Your Kubernetes cluster must span multiple availability zones. You can verify this by checking the labels on your nodes. Run
kubectl get nodes --label-columns=topology.kubernetes.io/zone. You should see at least two different zone values. - Label Awareness: Ensure your nodes have the standard topology labels. Most managed Kubernetes services (EKS, AKS, GKE) provide these automatically. If running self-managed, you may need to configure cloud-init scripts to apply these labels during node bootstrapping.
- Kubectl Access: Administrative access to the cluster to create and inspect resources.
- Understanding of Labels and Selectors: You must understand how to tag pods with labels and how selectors match those tags. Anti-affinity rules depend entirely on accurate labeling.
Hands-On Walkthrough
We will deploy a simple web application consisting of three replicas. We will demonstrate how to configure the Deployment manifest to ensure these replicas never coexist in the same availability zone.
Create a file named deployment.yaml.
apiVersion: apps/v1
kind: Deployment
metadata:
  name: web-app-ha
  labels:
    app: web-app
spec:
  replicas: 3
  selector:
    matchLabels:
      app: web-app
  template:
    metadata:
      labels:
        app: web-app
    spec:
      # Define anti-affinity rules here
      affinity:
        podAntiAffinity:
          requiredDuringSchedulingIgnoredDuringExecution:
          - labelSelector:
              matchExpressions:
              - key: app
                operator: In
                values:
                - web-app
            topologyKey: "topology.kubernetes.io/zone"
      containers:
      - name: nginx
        image: nginx:1.25
        ports:
        - containerPort: 80
        resources:
          requests:
            memory: "64Mi"
            cpu: "250m"
          limits:
            memory: "128Mi"
            cpu: "500m"
Breaking Down the Manifest:
- spec.replicas: 3: We want three instances for redundancy.
- metadata.labels.app: web-app: This label identifies our pods. It must match the selector inside the affinity rule.
- affinity.podAntiAffinity.requiredDuringSchedulingIgnoredDuringExecution: This is the hard constraint. The scheduler must obey this rule.
- labelSelector.matchExpressions: This defines which pods to consider for the anti-affinity check. We look for pods with the label
app=web-app. This ensures we only spread our own pods, not unrelated system pods. - topologyKey: “topology.kubernetes.io/zone”: This is the most critical field. It tells the scheduler that the “boundary” for separation is the availability zone. No two pods matching the selector can reside in the same zone.
Apply the manifest:
kubectl apply -f deployment.yamlWait for the pods to enter the Running state:
kubectl wait --for=condition=ready pod -l app=web-app --timeout=120sVerifying It Works
To confirm that the anti-affinity rules are functioning correctly, we need to inspect the node assignments of our pods. We will use kubectl to list the pods along with their assigned nodes and extract the zone information from the nodes.
Run the following command to display the pod names, their assigned nodes, and the zones of those nodes:
kubectl get pods -l app=web-app -o custom-columns="NAME:.metadata.name,NODE:.spec.nodeName,ZONE:.status.hostIP"
| xargs -I {} kubectl get node {} -o jsonpath='{.metadata.labels.topology\.kubernetes\.io/zone}{"\t"}'
| paste - <(kubectl get pods -l app=web-app -o jsonpath='{.items[*].metadata.name}') | awk '{print $2, $1}'
While the command above is complex, a simpler verification method is to describe the nodes:
kubectl get pods -o wideLook at the NODE column. Then, run kubectl get node <node-name> --show-labels for each unique node to see its zone. You should observe that the three pods are distributed across at least two different zones, and ideally three if your cluster has three zones available.
Expected Output Explanation: If you have three zones (us-east-1a, us-east-1b, us-east-1c), you expect one pod in each zone. If you only have two zones, you will see two pods in one zone and one in the other. Crucially, you will NOT see all three pods on the same node or even the same zone if the hard constraint is active and sufficient capacity exists.
If the pods remain in Pending status, check the events:
kubectl describe pod <pod-name>You will likely see an event indicating that the scheduler could not find a node satisfying the anti-affinity requirements, usually due to insufficient resources in other zones.
Common Mistakes
Implementing affinity rules seems straightforward, but several pitfalls can lead to unexpected behavior or cluster instability.
Mistake 1: Using Soft Affinity for Critical HA Requirements
Developers often use preferredDuringScheduling... (soft) thinking it helps with balancing. While soft affinity is useful for load balancing, it does NOT guarantee high availability. If the scheduler finds a node in Zone A that has slightly better metrics, it may place all replicas there, violating your HA intent. Always use required (hard) anti-affinity when you strictly require distribution across failure domains.
Mistake 2: Incorrect Label Selectors
The labelSelector inside the anti-affinity rule determines WHICH pods are being avoided. If you leave it empty or mismatched, the rule applies to ALL pods in the cluster. This can cause massive scheduling failures because your app tries to avoid every other workload in the cluster. Always scope the selector to your specific application labels (e.g., app=myapp). Conversely, if you want to spread different tiers (e.g., frontend vs. backend), you must carefully construct cross-selectors, but this is advanced and prone to error.
Mistake 3: Ignoring Resource Availability
A required anti-affinity rule is a hard constraint. If your cluster has limited capacity in Zone B, and all your pods are in Zone A, the scheduler cannot move a pod to Zone B unless there are free resources there. If Zone B is fully utilized, the pod stays in Zone A, breaking the anti-affinity rule's goal of distribution. This leads to Pending pods. Ensure your cluster has balanced resource capacity across all zones, or use mixed soft/hard rules if appropriate.
Mistake 4: Confusing Node Affinity with Pod Anti-Affinity
Node affinity pulls pods TO specific nodes. Pod anti-affinity pushes pods AWAY from other pods. Do not mix them up. If you want to ensure pods are on specific instance types (e.g., GPU nodes), use Node Affinity. If you want to ensure pods are not on the same machine or zone as peers, use Pod Anti-Affinity.
Mistake 5: Over-constraining with Topology Keys
Using kubernetes.io/hostname as a topology key spreads pods across different physical machines. Using topology.kubernetes.io/zone spreads them across zones. If you use both simultaneously in a required manner, you demand maximum distribution. This is good for HA but increases the risk of scheduling failures if the cluster is small. Start with zone-level anti-affinity for general HA, and only add hostname-level if you need protection against single-node failures.
Going Further
Once you have mastered basic zone anti-affinity, consider these production-grade considerations:
Scaling Implications: As your application scales to hundreds of replicas, zone-based anti-affinity becomes less effective because you simply run out of zones. In such cases, you may need to implement multi-region deployments or accept that some zones will carry higher loads. Consider using Horizontal Pod Autoscaler (HPA) in conjunction with anti-affinity to ensure that new replicas are always placed optimally.
Security and Isolation: Anti-affinity can also be used for security isolation. For example, you can prevent sensitive admin pods from running in the same zone as public-facing web pods, adding a layer of defense-in-depth against zone-specific compromises.
Performance Tuning: Frequent rescheduling due to changing cluster states can impact performance. Monitor the scheduler's efficiency. If you notice high latency in pod creation, review your affinity rules. Complex selectors can slow down the scheduler's evaluation loop. Keep selectors as simple as possible.
Alternative Approaches: Some organizations prefer using dedicated node pools for critical workloads and relying on node affinity to pin workloads to those pools. This offers stronger isolation but reduces flexibility. Another alternative is using external orchestrators or service meshes that handle traffic distribution, though this adds complexity. Kubernetes native anti-affinity is generally the preferred first-line defense for intra-cluster HA.
Disruption Budgets: Combine anti-affinity with Pod Disruption Budgets (PDBs). PDBs ensure that during voluntary disruptions (like node drains), the minimum number of replicas are maintained. Anti-affinity ensures those replicas are spread out. Together, they provide robust resilience.
Cleanup
To remove the resources created in this tutorial and avoid incurring unnecessary costs, run the following commands:
kubectl delete deployment web-app-haVerify that all pods associated with the deployment have been terminated:
kubectl get pods -l app=web-appThe output should be empty. If pods remain, force delete them (not recommended for production, but acceptable for cleanup):
kubectl delete pods -l app=web-app --force --grace-period=0Your cluster is now back to its original state, ready for the next experiment.
Architecture
References
This article was drafted with AI assistance and reviewed by the DevOpsEngine editors before publication.